Mathematics × Artificial Intelligence

Measuring what machine intelligence actually does.

I am Bowen Wang, a mathematics-trained researcher working across artificial intelligence and mathematical modelling, trustworthy computing, speech and multimodal intelligence, and cybersecurity. I develop mathematically grounded and verifiable AI methods for evaluation, reproducible benchmarking, trusted execution, LLM agents, and statistical risk modelling.
Current MSc researcher · Engineering with Artificial Intelligence · University of Bristol · 2026.09–2027.09
BSc Mathematics, University of Bristol · Upper Second-Class Honours

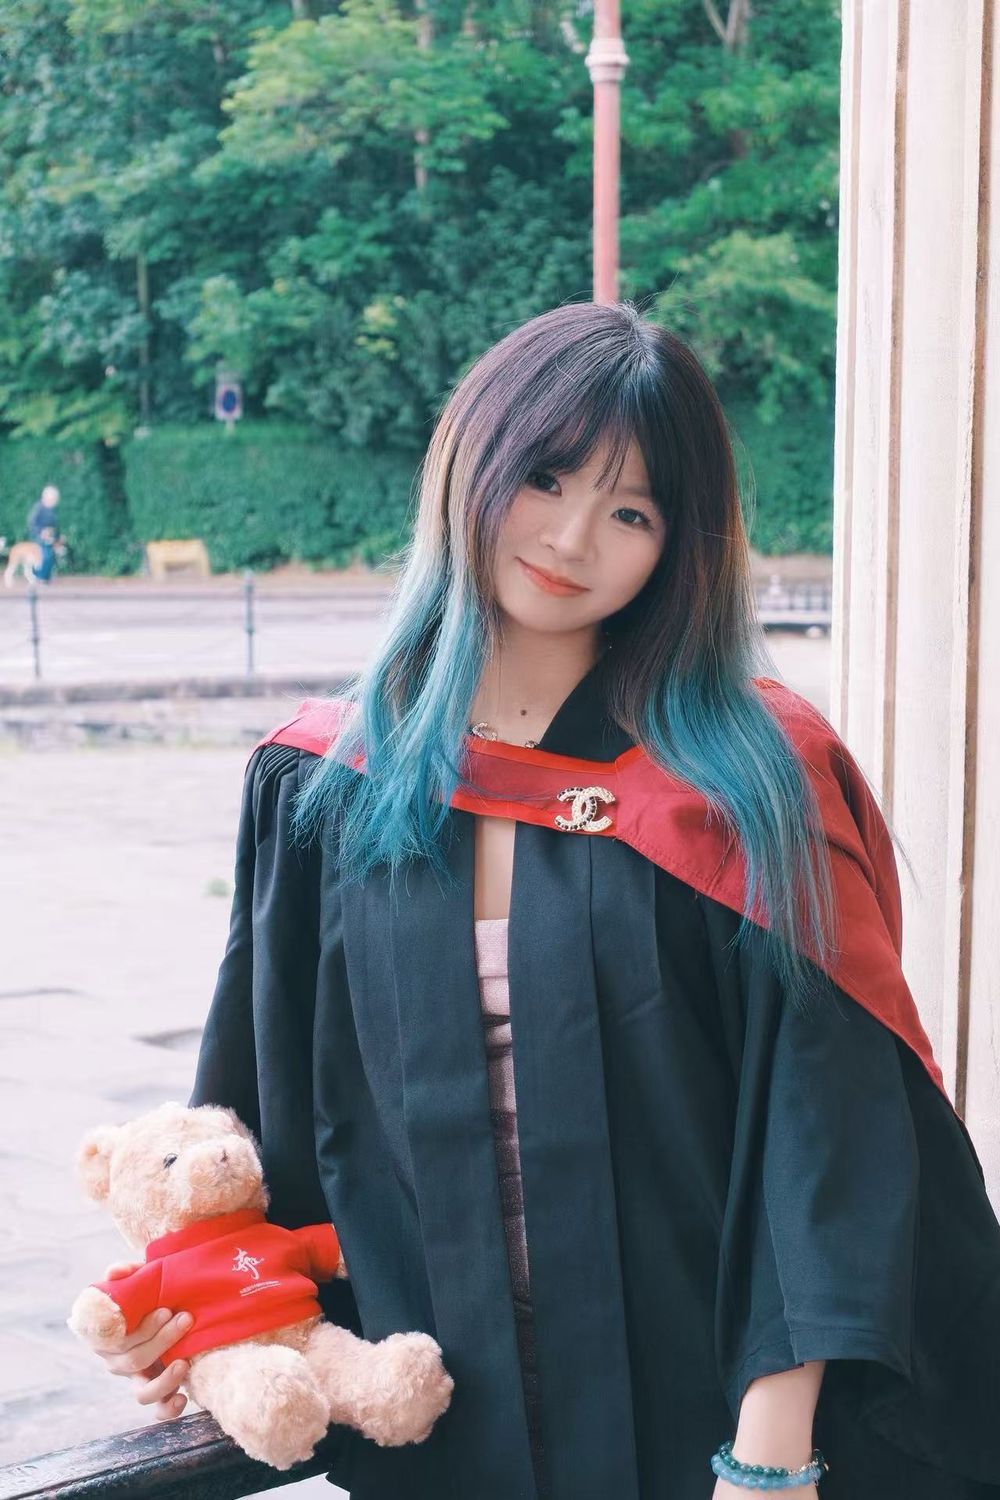
Portrait of Bowen Wang wearing University of Bristol graduation dress
Bowen Wang
Bristol, UK
Open to PhD
opportunities · 2027

Public speech & audio models

Standardised end-to-end in the SURE-EVAL onboarding workflow — one shared protocol for runtime and inference validation.

Bilingual policy paragraphs

Annotated through an LLM-assisted, human-verified pipeline for privacy and trustworthiness research.

Micro-F1 · evidence localisation

Reproducible baselines for locating the exact evidence spans that justify a compliance decision.

Research direction

Evaluation as a structured scientific problem.

My work asks how mathematical structure, reproducible systems, trusted execution, and agentic methods can make modern AI evaluation auditable — not merely scoring systems, but explaining when and why they fail.

Mathematical & Verifiable AIReproducible EvaluationTrusted Computing LLM AgentsSpeech & Multimodal AICybersecurity & Risk Modelling

How can AI benchmarks become reproducible, auditable, and independently verifiable?

Execution contracts, dependency validation, trusted environments, and attestation across changing models and systems.

Trusted executionReproducible benchmarking

How can mathematical structure help us design better AI evaluation metrics?

Optimisation, partial orders, and error decomposition that reveal failures hidden by aggregate scores.

Partial-order DPMetric decomposition

How should we model risk and reliability across complex, heterogeneous AI systems?

From overlapping speech and agent execution to privacy evidence and security-risk distributions, I study partially ordered, weakly aligned, and statistically structured information.

Temporal structureMultimodal evaluationStatistical risk modelling
“Reproducibility is not a final checkbox. It is the infrastructure that makes evaluation scientifically useful.”
— Working principle behind SURE, TEA for SURE, and SAER

Publications & current work

Research grounded in evidence, not headline scores.

  1. Accepted Accepted by NCMMSC 2026.03 — present

    SURE: Standardized Multimodal Model Onboarding and Reproducible Evaluation Framework

    Co-first Author · Prof. Kai Yu, IEEE Fellow · AI × Speech & Multimodal Intelligence × Systems

    • Standardised 18 public AI models across six speech and multimodal task families using unified execution contracts, ModelRegistry, dependency verification, and a four-stage validation pipeline — improving one-shot onboarding from 12/18 to 18/18.
    • Reproducibility experiments across seven ASR conditions and two TTS subsets identified 0.02–0.52-point protocol-dependent deviations.
    Project repository ↗
  2. Submitted to ICASSP 2027 2026.03 — present

    TEA for SURE: Trusted Evaluation through Attestation for Speech Model Benchmarking

    Co-first Author · Prof. Kai Yu, IEEE Fellow · AI × Trusted Computing × Hardware Security

    • Uses Trusted Execution Environments and remote attestation to cryptographically bind models, data, inference protocols, runtime environments, and evaluation outputs.
    • Intel SGX and Gramine experiments produced identical WER under trusted and direct execution while quantifying protected-execution cost; validation spans multiple ASR architectures and system ablations.
    Research manuscript · Submitted to ICASSP 2027
  3. In preparation Manuscript in preparation 2026.03 — present

    SAER: Mathematically Decomposed Evaluation for Speaker-Attributed ASR

    First Author · Prof. Kai Yu, IEEE Fellow · AI × Mathematics × Speech Intelligence

    • Formulates speaker-attributed ASR evaluation as a time-constrained partial-order dynamic programming problem and exactly decomposes cpCER − CER into speaker-consistency and cross-speaker order-relaxation terms.
    • AISHELL-4 and AliMeeting experiments study overlap, timestamp sensitivity, and speaker attribution, exposing hidden failure modes in conventional evaluation metrics.
    Manuscript in preparation
  4. Earlier peer-reviewed work

Research experience

From trustworthy data to reproducible multimodal evaluation.

Mar 2026 — present

Supervisor: Prof. Kai Yu, IEEE Fellow

Shanghai Jiao Tong University

Reproducible, trusted, and mathematically grounded AI evaluation

  • Co-developed SURE, a reproducible evaluation framework spanning 18 public models across six speech and multimodal task families.
  • Investigated verifiable benchmarking through Trusted Execution Environments, remote attestation, Intel SGX, and Gramine.
  • Modelled speaker-attributed ASR evaluation through time-constrained partial-order dynamic programming and exact error decomposition.

Jun 2025 — Mar 2026

Supervisor: Prof. Yan Zhang

Institute of Information Engineering, Chinese Academy of Sciences

LLM-Assisted Privacy Annotation and Security Risk Modelling

  • Designed a heterogeneous LLM workflow combining independent annotation, conflict critique, and human escalation across 28,000+ bilingual paragraphs, 13-way labels, and character-level evidence spans — reducing human intervention to 12.4%.
  • Built reproducible BERT-family baselines with evidence-span localisation reaching Micro-F1 = 0.91.
  • Combined Zipf/log-normal modelling, path n-grams, domain–path–parameter associations, and graph-based structural mining into interpretable security-risk scores evaluated with ROC/AUC, KS, Precision@K, and Recall.

Selected projects & competitions

Reproducible, trusted, and mathematically valid evaluation.

Accepted by NCMMSC

Reproducible AI evaluation

SURE-EVAL

A standardized onboarding and evaluation workflow for heterogeneous speech, audio, and multimodal models.

models passed one-shot onboarding after validation redesign
View integration notes ↗
Submitted to ICASSP 2027

Trusted AI evaluation

TEA for SURE

Verifiable speech-model benchmarking that binds models, data, protocols, runtime environments, and outputs through Trusted Execution Environments and remote attestation.

Intel SGX and Gramine experiments matched direct-execution WER while measuring protected runtime cost
Remote Attestation · Trusted Computing · Hardware Security
Manuscript in preparation

Mathematically valid evaluation

SAER

A time-constrained partial-order formulation that decomposes lexical recognition and speaker-attribution behaviour in multi-speaker ASR evaluation.

exact cpCER − CER decomposition tested on AISHELL-4 and AliMeeting
Partial-order DP · Combinatorial Optimisation · Speech Intelligence

Competition · Other project

Decoding Feline Pain

Project Leader · 2025.05–2026.03

The Aegis Professor Undergraduate Competition image-classification project compares keypoint-based MLP and Random Forest pipelines with a full-image CNN, using systematic occlusion experiments and Grad-CAM to examine the relationship between predictive performance and interpretability.

View code and schema ↗

Open-source competition · Tencent Rhino-Bird Program

OpenTenBase AutoVector

Individual Entry · In Progress

Vectorized-execution optimization for OpenTenBase, a PostgreSQL-based distributed HTAP database. All 9 performance targets passed with PASS/ACCEPT verdicts, with portable P95 latency reduced by 56–68% on identical hardware.

View repository ↗

Data competition · 2026 UN Data Marathon China

HeatSafe 2030

Team Member · 2026.07–Present

Urban Heat Action Intelligence: turning climate, urban-environment, and social data into understandable, comparable heat-risk information for city decision-making, presented as an interactive web experience. Advanced to the national Top 12 of the 2026 UN Data Marathon China round.

Visit project site ↗

Education

A mathematical foundation for responsible AI.

2026.09 — 2027.09 Current

MSc Engineering with Artificial Intelligence

University of Bristol · Bristol, UK

Foundations of Artificial Intelligence · AI Driven Design and Simulation · AI in Engineering Practice · Large-Scale Data Engineering · Software Development: Programming and Algorithms

2023.09 — 2026.06 Completed

BSc Mathematics, 2:1 Class Honours

University of Bristol · Bristol, UK

Statistical Machine Learning · Stochastic Optimisation · Mathematical Programming · Optimisation · Probability and Statistics

Let’s connect

I am interested in PhD opportunities starting in 2027.

If your group works on AI evaluation, agent reliability, mathematical machine learning, or multimodal systems, I would be glad to hear from you.

wwwency2003@outlook.com